IoT Platform & Connection System Suite
Asset Remote Monitoring
Asset Remote Monitoring securely monitors off-site equipment status, metrics and faults, sending contextual alerts to accelerate remote troubleshooting.
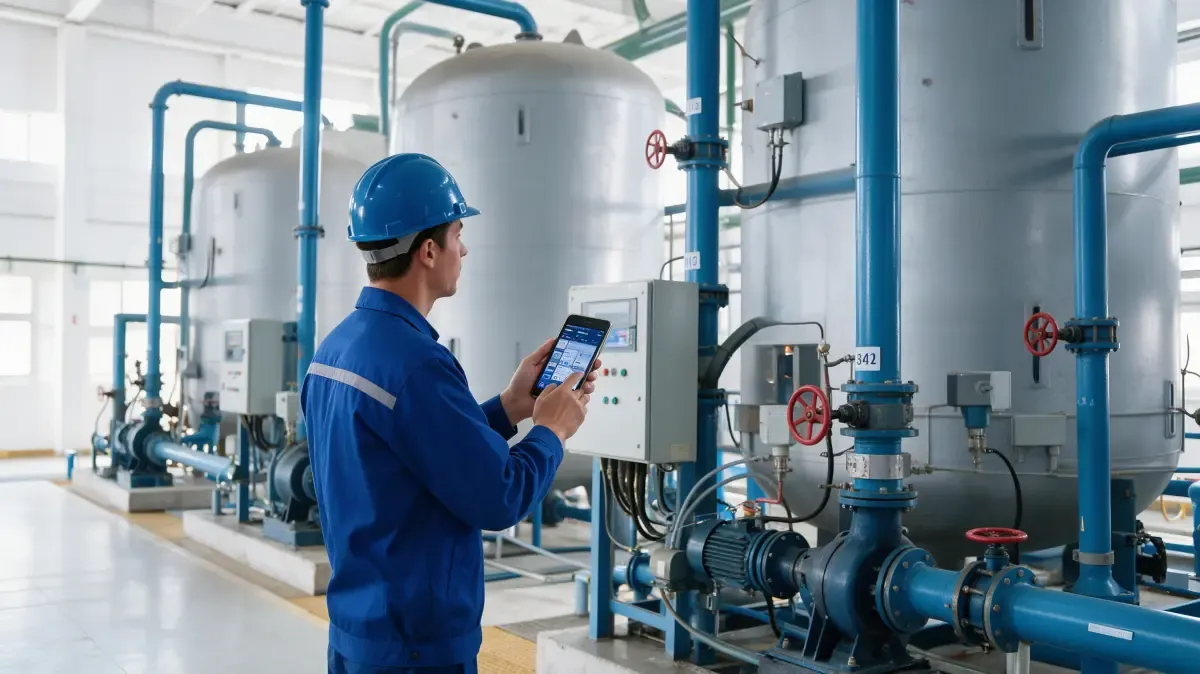
Something is wrong at a site nobody is standing at. What arrives is a fault code, or a value out of range, or nothing at all — just a light on a panel that somebody has to go and look at.
Asset Remote Monitoring keeps watch over equipment that is not in front of you: current status, the values that matter, faults, and the history behind them, with remote access granted under the permissions the site has set.
Remote access on its own is not much use. What makes it useful is context — which asset, where it is, what it was doing beforehand, what changed, and who is responsible for it. Without that, remote support is guesswork conducted at a distance.
Remote access without context is remote guessing.
What it is
An asset record with a current state. Each asset carries what it is, where it is, who owns it, and what it is reporting now.
Faults that arrive with context. An alert comes with the asset, its location, when it started, what the values were beforehand, and what happened before it.
Remote access that is controlled. Who may connect, what they may do, and how long a session lasts are set by the site, and sessions are logged.
Thresholds and rules per asset. What counts as a fault is configured per asset type and per unit, not applied uniformly across the estate.
History that a review can use. Values, faults, acknowledgements and actions are kept together, so an incident can be looked at afterwards.
A route into maintenance. A fault can become a work order that carries the asset record with it, instead of a message that has to be retyped.
What gets in the way today
Support starts with a phone call. Someone has to describe what they can see.
The person on site describes what is on a screen, and the person off site tries to picture it. Both are working from a partial view.
Somebody drives out to look at a display. Because that is the only way to see what the machine is saying.
The trip costs more than the problem. Which is known, and still happens, because there is no alternative.
Alerts without context. A code arrives; everything around it is missing.
A fault code arrives with nothing to say which unit raised it. So the first job is identifying the patient.
Nobody knows when it started or what the values were beforehand. Which is usually the information that would explain it.
The same code means different things on different machines. So experience substitutes for data.
Remote access is uncontrolled. Who can reach the equipment is not really known.
Who may connect, and what they may do once connected, is not recorded anywhere. It works because it has always worked.
A supplier's remote account stays open long after the job ended. Because closing it is nobody's task.
When something goes wrong, there is no record of who was connected. So the question cannot be answered.
Faults and maintenance are disconnected. The alert and the work are separate systems.
An alert is raised and nobody is obliged to act on it. So whether it was handled depends on who noticed.
When a work order is raised, it does not carry the asset's condition with it. So the technician starts from nothing.
What was found and what was done never comes back to the alert. So the same fault looks new next time.
What it monitors
Different asset classes are watched for different things. What is common is that a reading arrives with the asset, its place and its history attached.
Asset class | What is watched |
Production equipment | Running state, cycle behaviour, fault codes, the process values that matter for that unit |
Utilities and services | Compressors, chillers, pumps and fans: load, temperature, vibration where measured, run hours |
Metering and instrumentation | Readings, out-of-range conditions, and whether the instrument is still reporting |
Mobile and distributed assets | Location, operating hours, and where the next service falls due |
Remote sites | Power supply, environment, access and communications — the things that fail when nobody is there |
What can be monitored depends on what the asset reports. A machine that publishes its own fault codes gives more than one that only shows a running signal, and an instrument with no communication path cannot be watched at all. Where data is missing or stale, that is marked rather than filled in. The application watches and reports; it does not act on equipment, and the decision about what to do stays with the people responsible for the site.
What you get
Where it is used
What changes between these settings is what the assets are and what being remote costs.
Setting | What remote monitoring usually covers |
Multi-site manufacturing | Equipment at plants nobody senior sits at, watched from wherever the responsible engineer is |
Machine builders and OEMs | Machines in the field: condition, faults, and service intervals for equipment the builder still supports |
Utilities and infrastructure | Pump stations, substations and remote installations where a visit is a journey |
Process industries | Instrumentation and rotating equipment spread across a large site |
Facilities and estates | Building services — heating, cooling, power — across several locations |
Capabilities
Grouped by what they do. Device connection, identity and lifecycle sit with RUIYI IOTS Platform; this application uses that record to watch assets and handle what they report.
Capability | What it means |
Asset record | Keep what the asset is, where it is, who owns it, and its current state in one place. |
Status tracking | Show current condition and the values that matter, updated as the asset reports them. |
Fault raising | Raise faults from status, codes or out-of-range values, with what triggered them recorded. |
Context on every alert | Attach the asset, its location, when it started, preceding values and recent history. |
Thresholds per asset | Configure what counts as a fault per asset type and per individual unit. |
Severity and routing | Grade faults and route them to the person or role responsible for that asset. |
Acknowledgement and escalation | Require acknowledgement, and move it on if nobody does. |
Suppression | Mute what is expected — planned maintenance, scheduled shutdowns — so the queue stays readable. |
Remote access sessions | Grant access under the permissions the site sets, with what was done and for how long recorded. |
Access logging | Log who connected, to what, and when, so the question can be answered afterwards. |
Work order handoff | Raise a fault into the maintenance system as a work order carrying the asset record. |
History and replay | Look back at what an asset reported, including the period around a fault. |
Trend and drift | Show slow change over time, which a single reading rarely reveals. |
Ranking | Order assets by how often they fault or how much attention they take. |
Search | Find assets by name, location, type, owner or state. |
Deployment choice | Run in the cloud or on site, usually decided by where operational data may be processed and stored. |
Access and retention | Role-based access per site and area, retention set by policy, with access and changes logged. |
How it works
Register the asset. The asset is recorded: what it is, where it is, who owns it, and what values it reports, using the device record already held in the platform.
Set what matters. Thresholds and rules are configured for that asset type, and adjusted per unit where one differs.
Watch. Status and values are tracked as the asset reports them, and data that stops arriving is marked as stale.
Raise with context. A fault is raised carrying the asset, its location, when it started and what led up to it.
Route and act. It goes to the person or role responsible; if it is not acknowledged it moves on, and it can be raised as work.
Record the outcome. What was found and what was done come back to the asset record, so the next occurrence is not mistaken for a new one.
Access, security and boundaries
Access is granted, not assumed. Who may connect to which assets, what they may do, and how long a session lasts are configured by the site. Every session is logged.
Suppliers and service partners. Access for people outside the organisation is time-bounded and recorded, rather than left open after a job finishes.
What it does not do. It watches, reports and provides controlled access. It does not act on equipment, and it does not take over the safety decisions that belong to the people on site.
What depends on the asset. What can be monitored is limited to what the asset reports. Where nothing is available, that is shown rather than filled in.
What is local. Remote access policy, data residency, retention and any sector-specific duties depend on the jurisdiction and the site. Configuration is set to fit them; the system does not make those decisions.